MIYAIP · CRAWLER API
Reddit Scraper for Posts and Top-Level Comments
Use the MIYAIP Reddit scraper interfaces to collect a subreddit post list or the top-level comments on a Reddit post. Select the task in Crawler API, supply the parameters shown for that interface, and retrieve its result through a task ID.
Choose the collection target first. A list of subreddit posts and the comments under one post are different tasks. They have separate interface definitions, required inputs and credit costs.
Choose the Reddit collection task
| You need | Select | Check before starting |
|---|---|---|
| Posts from a subreddit list | Reddit Subreddit List | The target URL format, case-sensitive URL handling, supported limits and enabled state |
| Top-level comments from one post | Reddit Post Comments | The accepted post input, supported limits and current parameter definition |
These are the Reddit tasks listed in the Crawler API catalog. The signed-in interface definition gives the exact input keys and types. The comments interface returns top-level comments.
For a research workflow, keep the target, collection time and returned identifiers with the data. This makes later samples easier to compare, especially when a discussion changes between runs.
From a target to a saved result
-
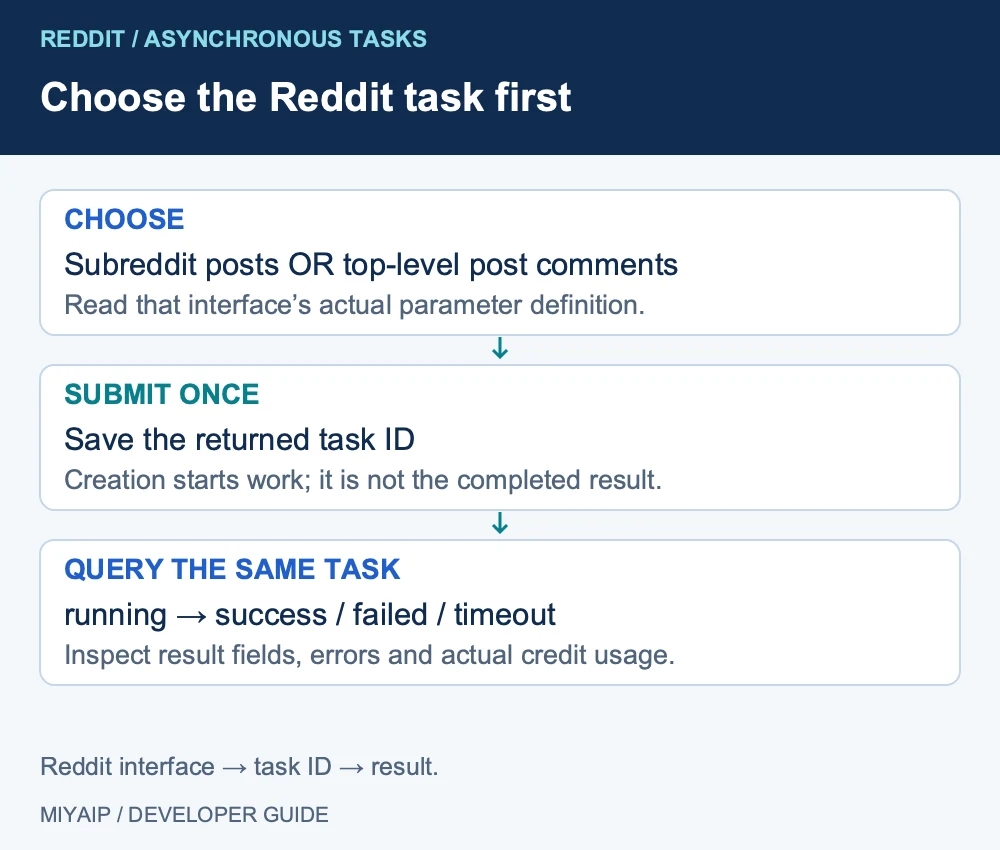
Open the interface catalog. Select the Reddit task that matches your target. Confirm that it is available to your account.
-
Read the current parameters. Check required fields, types, defaults and limits. For subreddit-list collection, preserve the URL's case as required by the interface.
-
Submit one small task. Review the displayed cost information and start the invocation. Save its returned task ID.
-
Query that task. Retrieve its state and result by task ID. Continue querying a running task instead of creating a second invocation.
-
Inspect the data and charge. Review the returned fields, errors and
costCreditsin the result and call log before increasing the workload.
Save the task ID after creation. When the task reaches a terminal state, inspect result and confirm that its records support your analysis.
Connect the Reddit scraper to your application
Crawler API uses the console login token described in its documentation. An MCP key belongs to the separate browser service. Discover the enabled interface and read its current parameter definition before constructing an invocation.
| Operation | Endpoint | What to retain |
|---|---|---|
| Discover interfaces | GET /api/CrawlerInterface/List |
Actual InterfaceKey and enabled state |
| Read input definition | GET /api/CrawlerInterface/Detail |
The selected interface's ParamSchema |
| Submit a task | POST /api/Crawler/Invoke |
Returned taskId |
| Retrieve the task | GET /api/Crawler/TaskResult |
Status, result, errors and credits |
Build the request from a parameter object validated against that interface. This is the documented request envelope; reddit_params represents the object you prepared from its current definition:
request_body = {
    "InterfaceKey": selected_interface_key,
    "Params": reddit_params,
}
Use the authentication and task runner to submit the selected Reddit parameters and retrieve the task result.
If a creation request times out, check existing logs before submitting again. The server may have accepted it even when your client did not receive the response.
Inspect the output your workflow actually needs
Open a small result and map the returned fields into your data model. Read the post-list and comment results separately because the interfaces can return different structures.
| Check | Why it matters |
|---|---|
| Collection target and interface | Keeps post lists separate from comments under a post |
| Available identifiers and source references | Supports matching records and reviewing their origin |
| Returned text and other fields | Confirms the result supports the intended analysis |
| Requested limit versus returned count | Makes partial or smaller samples visible |
| Collection time and task ID | Connects downstream data to the invocation and call log |
Validate these checks against the actual result. Output fields, target availability and supported limits depend on the selected interface. A result can be an object, array or string, so inspect its structure before loading it into a table.
Understand Reddit task credits
Crawler packages provide credits and concurrency. Consumption depends on the selected interface and parameters. Where the interface exposes base and parameter-driven pricing, use its displayed cost metadata to estimate a task, then compare the estimate with returned costCredits.
Review the selected interface’s cost metadata and your package balance in the console. Retain the returned task ID and costCredits with each collection so you can reconcile usage with the call log.
Frequently asked questions
Does the Reddit scraper collect every nested reply?
The published Reddit Post Comments interface covers top-level comments. A workflow that requires nested replies needs an interface that explicitly supports that scope.
Can I specify any subreddit URL or item count?
Use the target format and bounds in the current interface definition. For the subreddit-list interface, follow its case-sensitive URL instruction. The interface definition shows its supported limits and availability.
Is Reddit data returned in the initial POST response?
The documented workflow is asynchronous. Creation returns a task ID; your application uses that ID to retrieve the status and result.
Can I use a proxy password or MCP key to authenticate?
Follow the Crawler API console-token authentication guide. Proxy credentials and MCP keys authenticate other connections.
Start with one Reddit task
Choose posts or top-level comments, inspect the interface definition, and review one small result before connecting it to a recurring workflow.